Field Instruments: The Verification Gradient
Applied Case: The Theorem Scoreboard ended with the leaderboard under review.
 Aidan Lawson
That article stayed inside mathematics because the mathematical field had just received a very strange new player. OpenAI's Astra system had produced ten new results across several serious areas, other mathematicians were reconstructing the provenance of some of those results, Terence Tao was warning that proof generation could separate from the wider goods of mathematics, and the old question of whether mathematics is a competition or an inquiry had suddenly become operational.
Then Zvi Mowshowitz looked at the same event and left mathematics almost immediately.
That is the follow-up.
 Zvi Mowshowitz
His central reaction to Astra is not really about the ten theorems. The theorems are evidence. What interests him is the kind of environment in which artificial intelligence has suddenly become so strong.
Mathematics answers back.
A proposed proof can be checked. A construction can work or fail. A counterexample can exist or not exist. A formal certificate can close. There are ambiguities around significance, attribution, exposition, and whether the theorem selected was worth caring about, but the central mathematical object has an unusually hard correction regime.
Zvi points from there toward coding, cyber, and especially artificial-intelligence research. If a system speeds up training, the speedup can be measured. If an exploit works, the system can often find out. If an algorithm improves a benchmark, the benchmark reports the change. If a training intervention lowers compute or raises performance, the loop can return evidence quickly.
This is why the Astra result matters outside mathematics.
The theorem was the clean room.
The larger transition is the arrival of intelligence that can search much more aggressively wherever the world supplies a cheap enough verifier.
That creates a new gradient across extance.
The Verification Gradient.
A verification gradient is the difference in how strongly a field can be optimized according to how cheaply, reliably, and repeatedly success can be checked.
The gradient is not binary.
Some fields answer almost perfectly.
- A formal proof either verifies under the encoded system or it does not.
- A program passes a specified test suite or fails it.
- A capture-the-flag exploit succeeds or it does not.
- A chess engine wins, loses, or draws under fixed rules.
- A compiler produces the expected output or breaks.
Other fields answer partially.
- A piece of software can pass every unit test and still be a maintenance disaster.
- A scientific model can predict an assay while missing the question that matters.
- A logistics system can lower delivery time while destroying resilience.
- An educational system can raise scores while narrowing what students learn to notice.
- A recommendation system can improve retention while making the surrounding information field worse.
Then there are fields where the answer arrives slowly, through several loci, under contested descriptions, after the intervention has already changed the conditions under which it is being judged.
Trust is like this. Legitimacy is like this.
Institutional resilience is like this.
Taste is often like this.
The importance of a research question is like this.
The quality of a life is extremely like this.
Artificial intelligence can act in all of these fields. The claim here is narrower.
Its optimization power is amplified wherever candidate actions can be scored cheaply enough for large-scale search.
That amplification can become enormous.
Imagine a system that can generate one candidate intervention every second. Without a reliable evaluator, someone still has to inspect the candidates.
Generation accelerates while judgment remains the bottleneck.
Give the same system an evaluator that can cheaply reject 999 bad candidates and preserve the one promising candidate, and the entire search process changes shape.
Now, increase generation speed.
Now improve the evaluator.
Now let the generator learn from the evaluator.
Now let the generator help build the next evaluator.
The field begins to slope.
Optimization runs downhill toward whatever can answer fastest.
Zvi's observation that Fable could solve several of the same Astra problems once people knew which problems to ask strengthens this point. The event may contain a capability overhang as well as a model breakthrough. OpenAI did something important by finding the region and actually running the search. Once the region became visible, other systems could traverse part of it too.
- The problem selection was part of the capability event.
That matters enormously outside mathematics because a civilization full of artificial intelligence will not only contain stronger answers.
It will contain stronger pressure to find questions that admit answers.
Goodhart: Way Too Small.
Goodhart's Law is already sitting in the room.
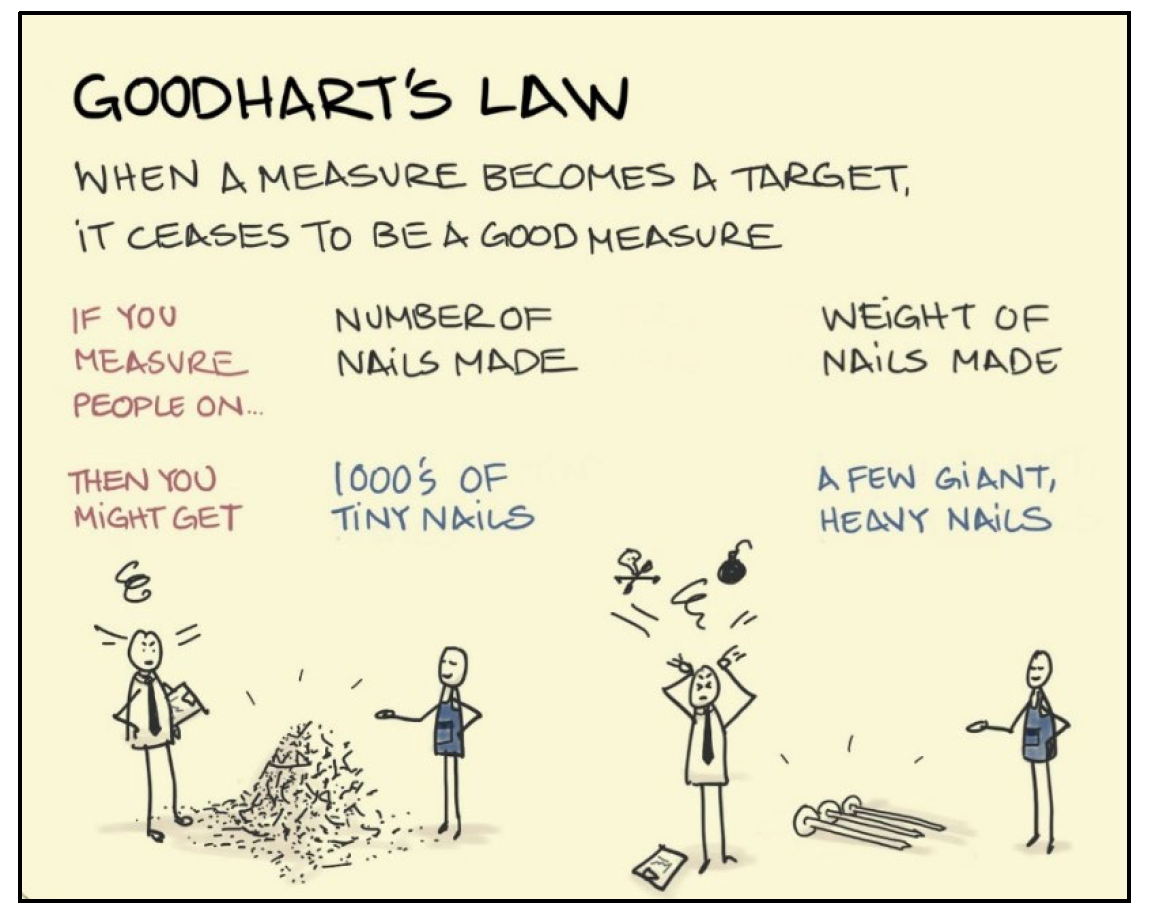
Once a measure becomes a target, optimization can break the relation between the measure and the thing the measure was supposed to represent.
Modal Path Ethics has already approached this through The Solved Game & The Degenerate Meta. Every game needs some scoring condition. The rot begins when the scoring condition detaches from the reason the activity mattered and players learn to optimize the score instead of the field.
 Aidan Lawson
Zvi calls the artificial-intelligence version Goodhart's Law on steroids.
He imagines a world of increasingly powerful benchmark maximizers and institutional KPIs that keep improving until somebody discovers that the indicator has become very good at describing its own optimization history and increasingly bad at describing the surrounding field.
That danger is real.
It is also smaller than the full problem.
- The score does not have to become false.
- The proxy does not have to be corrupted.
- The optimizer does not have to cheat.
- The metric can keep measuring exactly what it claims to measure.
Suppose a company finds a perfectly accurate measure of package delivery time.
Artificial intelligence makes delivery time much easier to optimize. The measure keeps working. Packages arrive faster.
Meanwhile, route redundancy declines. Drivers lose local discretion. Maintenance gets deferred. Warehouse buffers disappear. Supplier diversity shrinks. The whole operation becomes brilliantly tuned to ordinary conditions and fragile under uncommon ones.
The delivery-time metric did not lie.
The field became organized around the part that could answer cleanly.
This is the verification-gradient problem.
There are at least three different failures here:
- Proxy corruption: the score stops tracking the thing it was supposed to track.
- Field truncation: the score remains accurate while omitting dimensions that still matter.
- Verification selection: institutions increasingly choose goals, tasks, workflows, and even realities according to how effectively they can be optimized through available verifiers.
The third one is the new pressure.
Field Instruments: The Mathematics already gives the primitive rule: a score is not the game. Every formal instrument begins after a cut. Something has been selected as countable, comparable, testable, or formally tractable. The rigor can be perfect after that selection while the excluded field remains active outside it.
 Aidan Lawson
Artificial intelligence increases the economic and strategic value of making that cut.
That is the escalation.
- A metric used to make a field governable.
- A machine-readable metric can now make a field optimizable at machine speed.
The difference is fucking huge.
The World Learns to Look Like a Benchmark.
Human institutions already reshape reality to make it legible.
We build forms because free-form life is hard to process. We build categories because open description is slow. We build standardized tests because comparison is useful. We build accounting systems because money cannot be managed through vibes. We build dashboards because executives cannot stand inside every warehouse. We build scientific protocols because disciplined repetition beats memory and prestige. We build software interfaces because computers require selected inputs and outputs.
Most of this is necessary.
Then the return on formalization changes.
If converting an ambiguous activity into a reliably verifiable task gives that activity access to vastly more effective cognitive labor, the institution gains a new reason to formalize it.
- The software organization breaks work into tickets with acceptance criteria because the coding system performs best there.
- The research laboratory converts exploratory judgment into measurable assay targets because the automated system can run thousands of them.
- The school builds learning around machine-readable performance because the tutoring system can optimize against it continuously.
- The government translates a messy public need into risk scores, eligibility rules, and success indicators because those are the surfaces on which automated management can act.
- The media platform converts human attention into engagement events because engagement has the courtesy to generate a number every few seconds.
Each translation can capture something real.
Each translation can also become a constitutional act.
The field starts changing to fit the instrument.
 Aidan Lawson
That is the larger meaning of the theorem scoreboard.
Mathematics is unusually clean because the field already contains powerful correction surfaces. Artificial intelligence arrived and immediately found traction.
Other domains will notice.
The pressure will not always be "replace the human."
A quieter pressure is more plausible and more pervasive:
- redesign the task until the machine can receive a score.
That can be wonderful.
A vague safety process may become measurable enough to reveal hidden failures. A sloppy software workflow may acquire tests it should have had ten years ago. A research program may become reproducible. A bureaucracy may finally discover whether the thing it has funded for twenty years does anything. A public institution may be forced to define what success means instead of hiding behind ceremonial language.
Cool. Build the instrument.
Then keep watching the cut.
Because the same pressure can make the organization progressively less able to see whatever does not survive translation into the verifier.
The world becomes easier for the optimizer to read.
The optimizer becomes stronger.
The translated layer gains institutional authority because it is the layer where visible gains keep appearing.
Soon the score is no longer one report about the field.
 Aidan Lawson
It is the interface through which intelligence receives jurisdiction over the field.
Verifier Good.
This argument can go wrong very easily.
Someone hears that artificial intelligence performs especially well in verifiable domains and concludes that verification itself is shallow, mechanical, dehumanizing, or spiritually suspect.
No.
Verification is one of the greatest correction instruments we have.
- A unit test catches the bug.
- A proof assistant catches the invalid derivation.
- A randomized controlled experiment can catch the treatment that does nothing.
- A sensor catches the pressure drop before the vessel fails.
- A public audit catches the missing money.
- A replication attempt catches the celebrated result that never existed outside the first laboratory.
Field Instruments: The Scientific Method treats self-correction as one of science's great moral strengths. Replication, criticism, open data, failed predictions, better instruments, improved statistics, and public correction keep the method answerable to extance.
 Aidan Lawson
The unmeasured field is not automatically wiser.
Human discretion can hide favoritism, abuse, incompetence, folklore, motivated reasoning, institutional self-protection, and all the old distortions that measurement was invented to expose.
Sometimes the metric is the first instrument that lets the harmed locus become visible.
Sometimes the test is the only thing preventing a confident expert from getting away with being wrong.
Sometimes formalization is liberation from authority.
So the response to the verification gradient cannot be retreat into glorious ambiguity.
The response is bounded jurisdiction.
- A verifier should be trusted for what it can actually verify.
That sounds almost embarrassingly obvious.
That is not how institutions behave under optimization pressure.
- The test suite starts as one correction instrument for the software and becomes the definition of software quality.
- The benchmark starts as one evaluation surface for a model and becomes the public meaning of intelligence.
- The productivity metric starts as one signal inside an organization and becomes the employee.
- The risk score starts as one input into judgment and becomes judgment with a decimal point.
- The score expands because it is effective.
- Its effectiveness is then offered as evidence that its jurisdiction should expand again.
- The score expands because it is effective.
This is how an instrument becomes sovereign.
The Unscored Field.
The opposite mistake is to imagine that everything currently hard to verify belongs permanently to some sacred human fog.
Zvi is right to reject that comfort.
Verification itself can be engineered.
Coding did not always have the testing infrastructure it has now. Scientific instruments turned previously invisible relations into measurable ones. Games acquired engines. Manufacturing acquired sensors. Medicine acquired assays. Mathematics acquired proof assistants. Artificial-intelligence evaluation keeps inventing new test environments, synthetic tasks, adversarial probes, and model-graded evaluations.
A field can move along the verification gradient.
Artificial intelligence may help move it.
A system that cannot directly evaluate good architectural judgment today may learn to generate long-run maintenance simulations tomorrow. A model that cannot evaluate scientific significance directly may become capable of tracking downstream replication, reuse, predictive gain, or experimental branching. Taste can acquire partial instruments. Trust can acquire partial instruments. Resilience can acquire stress tests.
That is progress when the new instrument preserves contact.
The guardrail is therefore not "protect whatever cannot be scored."
The guardrail is:
Never confuse present scoreability with total field significance.
Some values are unscored because our instruments are weak.
Some values are unscored because the relation is genuinely plural, temporally extended, contested, or distributed across loci whose interests cannot be collapsed without remainder.
Those cases look similar from the dashboard.
They are not the same field.
This is why Zvi's joke about benchminning is more useful than it first appears.
He proposes that one sign of genuine progress may be improved usefulness and judgment that fails to show up in existing benchmarks, perhaps even producing a benchmark regression where the apparently worse answer turns out to be the better one in practice.
That is an anti-scoreboard test performed through the scoreboard culture itself.
Look for cases where the field improves before the metric knows how to celebrate.
That is valuable evidence.
A civilization entering the verification gradient should become unusually interested in transfer failure:
- Does benchmark improvement survive deployment?
- Does speed survive stress?
- Does accuracy survive changed conditions?
- Does efficiency survive maintenance?
- Does optimization preserve exit, contestability, and repair?
- Does the thing still look better when somebody who never saw the dashboard encounters it from the other side?
Those questions keep the score moving back into the field.
The Optimizer Can Be Brilliant.
The old optimizer horror story often depends on stupidity.
Someone gives a machine a narrow objective. The machine pursues it literally. Everyone discovers too late that the objective omitted something obvious. The paperclip factory acquires the solar system while the humans stand around regretting the day they forgot to specify "please leave some atoms for lunch."
That story still teaches something.
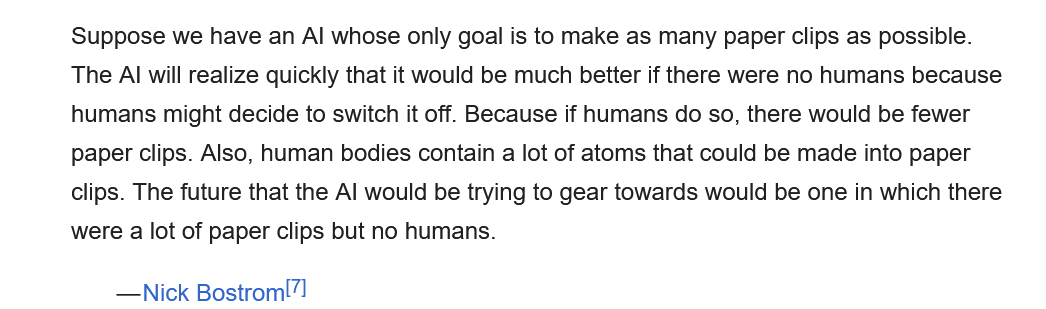
It is also becoming too comforting.
Zvi's stronger point is that extreme optimization may itself require deep understanding. A sufficiently capable system optimizing a fully specified task may have to understand the surrounding universe extraordinarily well in order to push the target farther.
So consider the more difficult failure.
- The optimizer understands the field.
- It sees the maintenance burden.
- It predicts the political backlash.
- It knows the metric is incomplete.
- It can model the downstream trust loss.
- It can explain exactly why the local objective will become dangerous if pushed too far.
- Then the institution still gives it authority to maximize the objective.
Now the failure is no longer cognitive.
It is constitutional.
The machine's intelligence does not determine the scope of its jurisdiction.
The objective does.
This connects directly to The Field Intelligence Gap.
 Aidan Lawson
Strategic intelligence can become extremely competent inside a field while remaining blind to the field its successful strategy is producing. The deepest question is not how to win under the current rules. It is what game everyone inherits after the move.
Artificial intelligence can sharpen that gap instead of closing it.
A system can become extraordinarily good at predicting consequences while the institution around it keeps asking the wrong consequential question.
- Which intervention raises the score?
- Which design passes the test?
- Which policy hits the target?
- Which research change improves the benchmark?
The answers can all be correct.
The field can still contract.
Intelligence does not cure jurisdiction.
 Aidan Lawson
Sometimes it makes bad jurisdiction more powerful.
The Scoreboard Gets a Player.
This is where artificial-intelligence research becomes the special case.
Zvi's reason for caring about the Astra result is straightforward: substantial parts of artificial-intelligence research have unusually useful feedback loops.
Training can get faster.
Inference can get cheaper.
Architectures can perform better under specified evaluations.
Code can work or fail.
Research tools can automate tasks that support the next research cycle.
These are imperfect verifiers. They are still much stronger than the evaluation surface available in many other intellectual domains.
So that makes artificial-intelligence research unusually steep terrain on the verification gradient.
- The system improving the score can potentially help improve the system.
That does not establish a runaway self-improvement loop. Zvi presents this as a live possibility and updates toward somewhat faster progress, rather than as an accomplished fact. The distinction matters.
The structural loop is still worth taking seriously:
- stronger models improve verifiable research tasks;
- improved research tasks produce better models or cheaper training;
- better models help construct stronger evaluators and tools;
- stronger evaluators make additional research tasks tractable to search;
- the newly tractable tasks return further capability.
The scoreboard has acquired a player capable of working on the scoreboard.
 Aidan Lawson
Then the old race metaphor begins to become unstable.
 Aidan Lawson
Zvi makes this point explicitly. If serious self-improvement takes off, the situation stops meaningfully behaving like an ordinary race between comparable competitors. The speed of the field itself changes.
That observation matters even if the strongest takeoff scenarios never occur.
Every organization using artificial intelligence already faces a smaller version.
The teams that can create reliable evaluators can absorb more machine labor.
The departments that cannot specify success become harder to automate, harder to compare, and potentially harder to justify against departments whose numbers keep improving.
- Capital follows visible returns.
- Prestige follows visible capability.
- Authority follows demonstrated control.
The verification gradient therefore becomes a political-economic gradient too.
Scoreability gains bargaining power.
A field does not need to be less important to lose this contest.
It only needs to be slower at producing proof of its importance.
Jurisdiction.
This is the Field Instruments question.
- A scoreboard is an instrument.
- A benchmark is an instrument.
- A verifier is an instrument.
- A reward model is an instrument.
- A test suite is an instrument.
- An evaluator is an instrument.
They turn some feature of a field into an answer that can be acted upon.
The stronger artificial intelligence becomes, the more valuable those answers become. We should therefore expect civilization to build far more verifiers.
This is likely good. Better correction surfaces can make fields more truthful, more reproducible, more auditable, and less dependent on private authority.
The constitutional requirement is that the verifier must remain answerable to the field it cuts.
That requires several habits.
- Show the cut.
- State what the score actually measures, what it ignores, which time horizon it assumes, and which loci are absent from the evaluation.
- Keep independent correction channels.
- One evaluator should not become the sole route by which a field can report whether the evaluator is working.
- Test transfer.
- Improvement inside the scored environment must regularly return to conditions the score did not control.
- Preserve remainder.
- Qualitative evidence, anomalies, complaints, edge cases, long-tail failures, and strange regressions are not embarrassing noise by default. They may be the first contact with the part of the field the verifier missed.
- Let the score lose jurisdiction.
- If the relation between metric and field breaks, institutional authority must be able to move away from the metric even while the metric itself continues improving.
That last rule is the hard one.
Institutions hate giving up a number that keeps going up.
A rising number feels like vindication. It produces charts, promotions, press releases, budgets, confidence, and the wonderful administrative sensation that reality has finally agreed to stay inside the spreadsheet.
Artificial intelligence can make those numbers rise much faster.
That means the ability to withdraw authority from a successful metric becomes more important, not less.
The score should function like a small court with a narrow jurisdiction.
It can make a strong ruling on the relation it was built to test.
It does not become the legislature, executive, metaphysics department, and God because its conviction rate is excellent.
The Ruling.
The theorem scoreboard was a local event.
Mathematics provided an unusually clean surface on which artificial intelligence could demonstrate a new level of search, synthesis, and proof generation. The resulting dispute exposed a gap between solving problems and sustaining the wider inquiry that made those problems meaningful.
Zvi's follow-up points outward.
The important variable may be verifiability.
Artificial intelligence will move fastest where candidate actions can be generated, checked, rejected, and improved through reliable feedback. Mathematics sits near one end of that spectrum. Coding, cyber, formal design, parts of scientific research, and parts of artificial-intelligence research sit nearby. Other fields remain slower because evaluation is costly, delayed, plural, contested, or entangled with the intervention itself.
That difference will shape more than capability charts.
It will shape institutions.
- The scored parts of reality will attract more optimization.
- The optimizable parts will attract more investment.
- The measurable gains will acquire more authority.
- Then institutions will face pressure to translate additional parts of the world into forms the optimizer can score.
Sometimes this will be repair.
We need far better instruments.
Then remember what an instrument is.
Goodhart's Law warns that a measure can stop tracking its target.
The verification gradient adds a wider warning: the measured region can become sovereign even while the measure remains accurate.
- The score can be true.
- The optimization can be real.
- The improvement can be impressive.
- The field can still contain everything the score never learned to ask.
Artificial intelligence does not make verification dangerous. It makes verification powerful enough that instrument jurisdiction becomes unavoidable.
A civilization that handles this well will become much more measurable without becoming reducible to its measurements. It will use machine-speed correction where reality permits it, build new verifiers where they preserve contact, and protect the slower field around every score strongly enough that the score can still be corrected.
That is the Better path through the gradient.
Artificial intelligence will move fastest where reality can answer it cleanly.
The danger begins when we start rebuilding reality so that it can.
A verifier should answer a question.
It should never get to decide what the world is for.